Connecting a LLM Agent Harness to a Private Application: Hooks and a Local MCP Server
14 min read
- claude-code
- hooks
- llm-agents
- mcp
- private-apps
- proof-of-concept
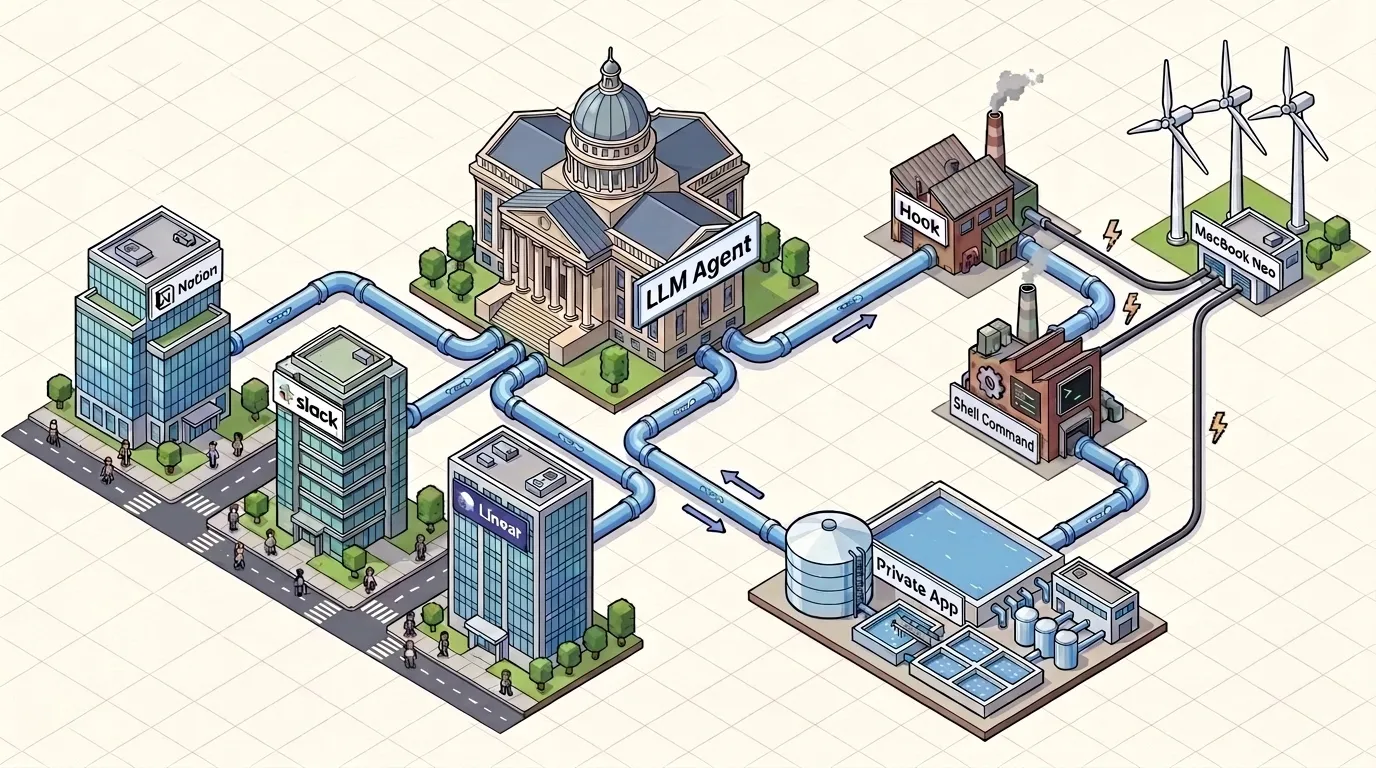
Large Language Models (LLMs) running inside an agent harness become a highly effective system when combined with team collaboration tools like Slack, Linear, and Notion, along with other agents and connectors. Together, they form a network of capabilities and connective tissue that an agent can both operate within and use to carry out a goal. As authentication, permissioning, and data protection improve for mixed teams of humans and agents, trust in these connected systems, and their use, will grow. Anthropic’s marketplace is one example of continued investment in this kind of connectedness. For individuals, the barrier to entry into this ecosystem is also dropping dramatically, making this space an open playground for exploring and testing ideas. Here, I walk through a simple proof of concept (POC) to better understand how a private application can connect to this growing ecosystem of publicly accessible third-party tools.
Overview of Tooling Scaffold and Framework
A framework for an integrated personal application:
- Create an application you want to regularly interact with, and make it accessible to the LLM Agent. In this case, I have an application in the form of a Python package committed as a standalone repo in Github. I want to use that application to store and retrieve data via a LLM Agent and tooling ecosystem. All of this operates via my local environment (MacBook Neo) with an installation of Claude Code and using either APIs, CLI, or a MCP server.
- Create a hook within the LLM Agent and use it to call your application. A hook will be triggered by some event of your choosing. For example, I’ve set the hook to trigger after a “turn” within Claude Code. Why a hook vs. adding instructions into the prompt? For data curation and submission, I want a reliable execution of deterministic code having known meaning.
- Connect the hook to your application. Within the hook, add necessary elements to connect the underlying shell command to execute your application. I can load generated data into my application using a python script, and may call that script through the shell string using the hook command respected by Claude Code.
- Separately, connect the LLM Agent to your application using MCP. To provide the LLM Agent with native access to the private application for data retrieval, I have connected a local MCP server full of agent-specific functionality and with a deliberate agent safety boundary.
- Test. Run a triggering event and verify the output.
Fig. 1: LLM Agent interacting with both private and public applications. A LLM Agent triggers a hook, which executes a shell command, which executes functionality of a private app. The private app has a bidirectional relationship with the LLM Agent using a local MCP server, and the LLM Agent has a bidirectional relationship with public applications. The lightweight hook, shell command, and private app are all powered locally with minimal compute requirements.
Install the Private Application
I have a simple application in private Github repo: A Python package which can accept data, load it into a table, and then make that data available for query through either CLI or MCP. To connect the application to Claude Code, I set my working directory to the project, semontos, added the local MCP server, semontos-mcp, and set access to be at the user level using --scope user.
semontos % uv tool install .
Resolved 32 packages in 183ms
      Built semontos @ file:///Users/keegan/Github/semontos                                                             Prepared 1 package in 329ms
Uninstalled 1 package in 1ms
Installed 1 package in 1ms
 ~ semontos==0.19.0 (from file:///Users/keegan/Github/semontos)
Installed 2 executables: semontos, semontos-mcp

semontos % claude mcp add semontos -- semontos-mcp
Added stdio MCP server semontos with command: semontos-mcp  to local config
File modified: /Users/keegan/.claude.json [project: /Users/keegan/Github/semontos]

semontos % claude mcp list
notion: https://mcp.notion.com/mcp (HTTP) - ✔ Connected
semontos: semontos-mcp  - ✔ Connected
Designing a hook
Now that the application is accessible to the LLM Agent, let’s create a simple hook and generate some data. A hook is a good step to take when there is a need for a regular and deterministic action during a session with a LLM. In this POC, I simply want the hook to derive data and inform me of session usage at the turn-by-turn level, so that I may track and monitor token usage. All agent harnesses seem to have the ability to use a hook, and there is substantial documentation for how hooks are implement (see Hook documentation for Claude Code, Codex, and Grok).
Establish the hook
POCs are different than developing for production, and all I need to show is a simple, viable looping path for how data will travel in the system. So, I’ll just ask Claude to set this up. From the Claude Code CLI:
> Hi Claude, create a hook to fire after every Turn. The hook should print out the total count of tokens used for both the prompt I supplied and for your response in the turn, along with number of seconds it took for the entire turn (my prompt, your action, and your respose) to execute. I also want a unique identifer for the turn and the EPOCH at time of print.Without exiting the session, Claude has established and implemented the hook:
I added the hook. It runs when each turn ends and prints one line like this (from a test run against this conversation):

Turn 14909b7d-f89f-4f5d-afcd-cfcba5d4d119 | prompt: ~89 tok (your text), 401128 tok input incl. context over 4 API call(s) | response: 2324 tok | duration: 37.6s | epoch: 1790879551

The test run worked and the settings file is valid. I haven't seen it fire at the end of a real turn yet. It should appear when this reply finishes; if it doesn't, open /hooks once or restart Claude Code so it picks up the new setting.

What's in place:
- Script: ~/.claude/hooks/turn-stats.py. It reads the conversation log to get the numbers.
- Settings: a Stop hook in ~/.claude/settings.json, added alongside your existing settings. It applies to every project.

What each field means:
- Turn ID: the unique ID Claude Code gives your prompt message.
- Prompt tokens: I report two numbers here, because Claude Code doesn't record how many tokens your typed text alone used:
  - ~N tok (your text) is an estimate: the number of characters divided by 4.
  - N tok input incl. context is the exact number of input tokens actually used. It adds up every request I made during the turn, and each request resends the whole conversation, so it's much bigger than your prompt.
- Response tokens: the exact number of output tokens I generated during the turn, including thinking and tool calls.
- Duration: time from when you sent the prompt until the hook runs, so it covers my tool calls and response.
- Epoch: Unix time in seconds when the line prints.

The line is only printed, not saved anywhere. If you'd like each line appended to a log file as well, that's a one-line change. You can turn the hook off or edit it in /hooks.
Stop says: Turn 14909b7d-f89f-4f5d-afcd-cfcba5d4d119 | prompt: ~89 tok (your text), 650116 tok input incl. context over 6 API call(s) | response: 2798 tok | duration: 49.0s | epoch: 1790879562

✻ Crunched for 49s · done 11:08 AM

※ recap: You asked for a hook that prints token counts, turn duration, a turn ID and the epoch after every turn, and it's now set up in your settings and passed a test run. Next, check that the line appears after a real turn; if it doesn't, open /hooks once or restart. (disable recaps in /config)
And there, near the bottom of the response is the requested output: Stop says: Turn 14909b7d-f89f-4f5d-afcd-cfcba5d4d119 | prompt: ~89 tok (your text), 650116 tok input incl. context over 6 API call(s) | response: 2798 tok | duration: 49.0s | epoch: 1790879562. Easy. We now have a hook that fires after each turn and surfaces data. I didn’t have to write any code, other than a prompt to initiate code. At a first pass, this is a great and simple foundation.
Connect Hook to Private Application
I installed my private application, semontos using uv and with Python 3.12. The problems are that (a) my system install of Python is Python 3.9.6 and (b) the system interpreter install doesn’t have access semontos. There are a myriad of ways to fix this. To keep use of the system install and still fix this particular installation specific problem, I’ll make changes to how the hook is called and to the script that is triggered by the hook.
The hook was established through a Claude-modified JSON object in settings.json which is accessible to all projects run by Claude:
keegan@macbook-neo ~ % cat ~/.claude/settings.json
{
  "model": "opus[1m]",
  "theme": "custom:pink-highlight",
  "agentPushNotifEnabled": true,
  "hooks": {
    "Stop": [
      {
        "hooks": [
          {
            "type": "command",
            "command": "python3 ~/.claude/hooks/turn-stats.py",
            "timeout": 15
          }
        ]
      }
    ]
  }
}
Instead of calling the system python3, I’ll use uv and update the command that is called to, "command": "uv run --script ~/.claude/hooks/turn-stats.py".
Next, I’ll need to update the python script which gets trigger, turn-stats.py, and provide it with additional context. Here is the unadulterated python script Claude created:
keegan@macbook-neo ~ % cat ~/.claude/hooks/turn-stats.py
#!/usr/bin/env python3
"""Stop hook: print token usage, duration, turn ID and epoch for the turn that just ended."""
import json
import sys
import time
from datetime import datetime

def is_real_prompt(entry):
    """A user-typed prompt, as opposed to a tool result or injected meta message."""
    if entry.get("type") != "user" or entry.get("isMeta") or entry.get("isSidechain"):
        return False
    content = entry.get("message", {}).get("content")
    if isinstance(content, str):
        return True
    if isinstance(content, list):
        return not any(isinstance(c, dict) and c.get("type") == "tool_result" for c in content)
    return False

def prompt_text(entry):
    content = entry["message"]["content"]
    if isinstance(content, str):
        return content
    return "".join(c.get("text", "") for c in content if isinstance(c, dict))

def main():
    payload = json.load(sys.stdin)
    with open(payload["transcript_path"]) as f:
        entries = [json.loads(line) for line in f if line.strip()]

    start = max((i for i, e in enumerate(entries) if is_real_prompt(e)), default=None)
    if start is None:
        return
    prompt = entries[start]

    # Assistant messages are split into one entry per content block, each repeating
    # the same usage, so count each API message id once.
    usage_by_id = {}
    for e in entries[start + 1:]:
        if e.get("type") == "assistant" and not e.get("isSidechain"):
            msg = e.get("message", {})
            if msg.get("id") and msg.get("usage"):
                usage_by_id[msg["id"]] = msg["usage"]

    input_tokens = sum(
        u.get("input_tokens", 0) + u.get("cache_creation_input_tokens", 0) + u.get("cache_read_input_tokens", 0)
        for u in usage_by_id.values()
    )
    output_tokens = sum(u.get("output_tokens", 0) for u in usage_by_id.values())
    prompt_est = round(len(prompt_text(prompt)) / 4)

    started = datetime.fromisoformat(prompt["timestamp"].replace("Z", "+00:00")).timestamp()
    now = time.time()

    msg = (
        f"Turn {prompt['uuid']} | "
        f"prompt: ~{prompt_est} tok (your text), {input_tokens} tok input incl. context over {len(usage_by_id)} API call(s) | "
        f"response: {output_tokens} tok | "
        f"duration: {now - started:.1f}s | "
        f"epoch: {int(now)}"
    )
    print(json.dumps({"systemMessage": msg}))

if __name__ == "__main__":
    main()
Instead of #!/usr/bin/env python3 I’ll add uv specific information to the header:
# /// script
# requires-python = ">=3.12"
# dependencies = ["semontos"]
# [tool.uv.sources]
# semontos = { path = "../..Github/semontos", editable = true }
# ///
Finally, I’ll import semontos and a few additional handling packages, initiate a client, add some a function to populate the semontos application, and make a few updates to the Claude Code in-shell reponse. For my current semontos app, I load data into the system through a structured csv. Loading a temporarily derived csv into an existing data model is a bit awkward and not production-worthy code right now (read, future semontos feature enhancement), however I am on a critical path for both this POC and in the development of semontos. This solution is perfectly fine for maintaining a faster speed of development right now:
...
import csv
import tempfile
from pathlib import Path
from semontos.client import SemontosClient

DATASET = os.environ.get("SEMONTOS_TURN_DATASET", "claude_turn_token_usage")
COLUMNS = ["turn_id", "total_tokens", "duration_seconds", "epoch"]
UNITS = {"total_tokens": "tokens", "duration_seconds": "s", "epoch": "s"}

...

def record(client: SemontosClient, row: dict, session_id: str | None) -> str:
    provenance = {
        "source_system": "claude-code",
        "producing_agent": "turn-stats Stop hook",
        "pipeline_run_id": session_id,
    }
    body = {"rows": [{c: row[c] for c in COLUMNS}], "provenance": provenance}
    try:
        result = client.append_json(DATASET, body, timeout=10)
        return f"appended as v{result['version']}"
    except httpx.HTTPStatusError as e:
        if e.response.status_code != 404:
            raise

    # First run: the dataset doesn't exist yet, and only a CSV load can create
    # one. `fail` rather than the default `replace`, so if another session
    # created it in the meantime this row is appended instead of starting a
    # reload that drops theirs.
    ensure_semantics(client)
    with tempfile.TemporaryDirectory() as d:
        path = Path(d) / f"{DATASET}.csv"
        with path.open("w", newline="") as f:
            writer = csv.writer(f)
            writer.writerow(COLUMNS)
            writer.writerow([row[c] for c in COLUMNS])
        try:
            result = client.load(
                path, DATASET, if_exists="fail", timeout=10,
                provenance={**provenance, "units": UNITS},
            )
        except httpx.HTTPStatusError as e:
            if e.response.status_code != 409:
                raise
            result = client.append_json(DATASET, body, timeout=10)
            return f"appended as v{result['version']}"
    client.bootstrap_attributes(DATASET)
    return f"created {DATASET} v{result['version']}"
A side note: Although there is nuance to this (see exec form), Claude Code sends the command within a hook as a string to be executed in a shell, and the hook inherits the parent environment. So, anything your user can do in that environment, the hook can do (i.e, run a bash script, run python, run cURL, etc.). Simple and powerful.
Verify Connections
I added the semontos data input connection and also slightly updated the message output within Claude Code’s message terminal (code not shown). Let’s test both the hook and the MCP server in a single turn.
The hook should fire after each turn with Claude Code and both add text near the end of Claude’s response and also populate my application, semontos, as it is running on my local MacBook Neo, effectively adding a new row to a database.
At the beginning of this post, I connect Claude Code to the MCP server of the private application: claude mcp add semontos -- semontos-mcp. The MCP server has much of the functionality of semontos, with a few deliberate agent boundaries. For example, I don’t allow for table/database deletes by the agent. However, I do allow for table creates, so let’s see how effective Claude Code is at establishing a new dataset in the system for later query outside of Claude Code.
Here is the prompt to test the hook and MCP server in Claude Code:
❯ Hi Claude! Find and load the famous "Iris" dataset into Semontos. Make sure to provide as much descriptive metadata about the data as is necessary. Also, please provide the name of the dataset, as you specify it in the system, so that I may look it up in the Semontos CLI by myself. Thanks!And Claude’s response:
  Ran 1 shell command

Now fetch the canonical Iris data from the UCI repository.

  Ran 5 shell commands

Now I'll build the CSV and the semantic definitions, then load everything through the API.

  Searched for 1 pattern, ran 3 shell commands

Loaded. Now the semantic layer: six attributes, mapped to the columns, and a class.

  Ran 2 shell commands

Quick sanity check of the stored rows and the corrected samples:

  Ran 1 shell command

The Iris dataset is loaded. The dataset name is iris.

semontos dataset info iris
semontos dataset query iris --filter species=Iris-virginica --order-by petal_length
semontos dataset version iris 1     # provenance and schema
semontos attribute mappings iris
semontos class info iris_flower

What's stored
- 150 rows (version 1), keyed on specimen_id. The columns are specimen_id, sepal_length, sepal_width, petal_length, petal_width and species.
- Source: the UCI Machine Learning Repository. I used bezdekIris.data, not the more common iris.data. The UCI file's own notes say iris.data has errors in samples 35 and 38 that don't match Fisher's 1936 paper, and bezdekIris.data is the corrected version. I checked rows 35 and 38 after the load and they now have the correct values.
- The only changes to the data: I added a header row and a specimen_id column, because the source file has neither. specimen_id is the row's position in the source file (1–150), which also matches the sample numbers in the UCI notes. All measurements and species labels are exactly as in the source, so species reads Iris-setosa, not setosa.
Stop says: Turn 6271bd67-c7df-43fc-9fee-4658f58fafe3 | total tokens 62940 over 14 API call(s) | duration: 101.4s | epoch: 1790890261 | Semontos: appended as v8

✻ Crunched for 1m 42s · done 2:31 PM

──────────────────────────────────────────────────── 1 new message ─────────────────────────────────────────────────────

※ recap: I loaded Fisher's Iris data into Semontos as the dataset `iris`, with provenance, six descriptive attributes and an `iris_flower` class, and nothing is pending. Next, look it up yourself with `semontos dataset info iris`. (disable recaps in /config)

────────────────────────────────────────────────────────────────────────────────────────────────────────────────────────
Great! I see the stop message: Stop says: Turn 6271bd67-c7df-43fc-9fee-4658f58fafe3 | total tokens 62940 over 14 API call(s) | duration: 101.4s | epoch: 1790890261 | Semontos: appended as v8. Now, let’s check that my application was updated with data. I have a CLI to access semontos on my local and can query the data based on key:value pairs:
keegan@macbook-neo ~ % semontos dataset query claude_turn_token_usage --filter turn_id=6271bd67-c7df-43fc-9fee-4658f58fafe3
{
  "dataset": "claude_turn_token_usage",
  "version": 8,
  "total": 1,
  "limit": 50,
  "offset": 0,
  "rows": [
    {
      "turn_id": "6271bd67-c7df-43fc-9fee-4658f58fafe3",
      "total_tokens": 62940,
      "duration_seconds": 101.4,
      "epoch": 1790890261
    }
  ]
}
Finally, let’s check the MCP connection:
keegan@Keegans-Mac-mini ~ % semontos dataset query iris | jq ".rows" | jq -r '["specimen_id", "sepal_length", "sepal_width", "petal_length", "petal_width", "species"], (.[] | [.specimen_id, .sepal_length, .sepal_width, .petal_length, .petal_width, .species]) | @csv' | head
"specimen_id","sepal_length","sepal_width","petal_length","petal_width","species"
1,5.1,3.5,1.4,0.2,"Iris-setosa"
2,4.9,3.0,1.4,0.2,"Iris-setosa"
3,4.7,3.2,1.3,0.2,"Iris-setosa"
4,4.6,3.1,1.5,0.2,"Iris-setosa"
5,5.0,3.6,1.4,0.2,"Iris-setosa"
6,5.4,3.9,1.7,0.4,"Iris-setosa"
7,4.6,3.4,1.4,0.3,"Iris-setosa"
8,5.0,3.4,1.5,0.2,"Iris-setosa"
9,4.4,2.9,1.4,0.2,"Iris-setosa"
Very nice. Claude was able to retrieve the data from the internet and then, using the MCP server, populate semontos with the Iris dataset.
What’s next?
I was able to verify the path of data and can generate and store data at regular cadence via a hook, or bring in data and store it as a “one off” from the wild using the semontos MCP server. The data was fully accessible offline in my private application.
Validation is an import step, and wasn’t a part of my POC. I didn’t post this, however Claude and I had a healthy discussion about what “total tokens” actually means. I started to dig into the session data and found that Claude Code captures JSON objects in a .JSONL file for each project in .claude/projects. Is the token count be appropriately accounted for? This needs to be evaluated and validated.
When exploring and reviewing the stored .JSONL files from my project activity, I also asked Claude about the schema of the JSON objects and received the following response:
Anthropic doesn’t publish or version the schema for these files, so there’s no official spec.
Indeed, I could not track down a public schema. Building a data pipeline on top of a schema-less, and potentially version-less source requires extensive checks and guardrails. For product-grade data capture, robust data checks and validation would need to be implemented to avoid meaning contamination or capture failures.
semontos is a new project and I have enhancements to make in both functionality and usability. Hands on testing of interaction with Claude Code has provided additional learnings, causing a reprioritization my of my roadmap items to work on and consider.